Agent Runtime & Evaluation Review
Before you give an agent more users, more tools or more autonomy, find out what it can actually touch, how it fails, and whether your tests would notice.
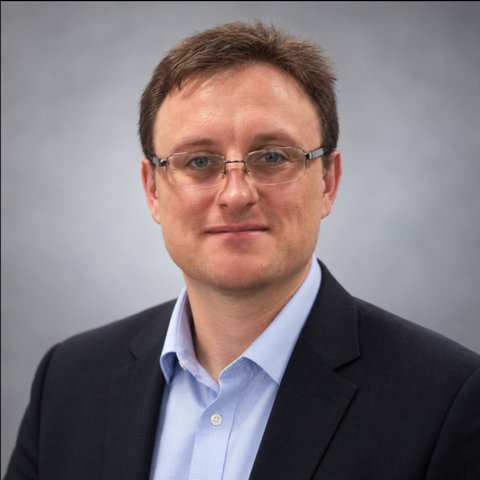
I'm Petar Kabashki. I've built software for 20+ years, much of it in banking, and most recently led GenAI and agent architecture at a large UK bank, including taking agentic designs through security and regulatory review. I build and audit agent harnesses, and I publish what I find in the notebook on this site. The review applies the same methods to your system in 2 weeks, at a fixed fee, and hands you written findings your team can act on.
The review
Agent Runtime & Evaluation Review · 2 weeks · fixed fee
An independent, evidence-based review of an agent system before you scale it: what it can touch, how it fails, what it really costs, and whether your evaluation would notice. It covers four areas:
Authority & blast radius
What the agent can read, write, execute and call. Credentials, sandbox boundaries, network egress, and where a human must approve.
Failure behaviour
How runs end: stop conditions, budgets, retries, repair loops, stranded work, and what happens when a tool or model misbehaves.
Evaluation & evidence
Whether your tests measure the deliverable or a proxy. Checks that can pass without running, metrics that hide failed jobs.
Cost & operations
Token and latency profile per completed task, context growth, concurrency, tracing, and whether an incident could be reconstructed.
What you get
- A written report: findings ranked by severity and effort, each with the evidence behind it and a concrete fix.
- A risk map of what the system can touch, and which actions should require a person.
- An evaluation gap list: what your current checks would and would not catch, plus a minimal regression suite to add.
- A 60–90 minute read-out with your engineers and the decision-maker. Questions are answered there, not in a sales deck.
- Two weeks of email follow-up while your team works through the fixes.
Every finding is labelled the way the writing here is: observation, inference, or provisional. You will know which claims are measured and which are judgement.
What a review finds
These are findings from my own systems, published in full. A review looks for the same failure patterns in yours.
An agent with shell access and no isolation behaves non-deterministically, and some of its failures are security failures.
Read: The Security Cost of Autonomy: Auditing 29 Runs →
A run can hit 100% task completion while the plan behind it is ungrounded: the model cited files that did not exist.
Read: Grounding Is Not Proof: 100% Code, 0% Plan Quality →
Cheap-looking token curves can coexist with incomplete deliverables. Efficiency only counts when the job is done.
Read: RLM Is Not Automatically Token-Efficient →
Network isolation is a design decision, not a flag. Here is what hardened sandboxing looks like end to end.
Read: Zero Net Access: Hardening LLM Agent Sandboxes →
Is this for you?
A good fit if
- You have an agent, RAG system or tool-using workflow in production or about to ship.
- It can take actions (run code, call APIs, change data), not just answer questions.
- You lead the platform or the architecture, and you need an outside read you can show to security, risk or leadership.
Not a fit if
- You want a chatbot installed, or a model vendor chosen for you.
- You need someone to approve a launch date rather than assess a system.
- Success is measured by a demo. I measure completed work, failure behaviour and cost.
After the review
Most teams fix the findings themselves; the report is written so they can. If you want help, these are the usual next steps:
Hardening sprint
I work alongside your team to implement the top findings: sandboxing, budgets and stop conditions, approval gates, tracing, and a regression suite.
Evaluation design
Task-level success criteria, deterministic checks around probabilistic behaviour, adversarial and prompt-injection tests, and reproducible sweeps.
Pilot or platform build
A bounded build of an agentic workflow or harness, with explicit tool contracts, least-privilege integrations, and an operational handover.
Ongoing advisory
A fixed number of hours a month for architecture reviews, design decisions and second opinions as your agent platform grows.
How I work
- Brief. You send a short written description. I reply within two working days with questions, a fit call if useful, and a fixed quote.
- Scope. We agree the system boundary, access, dates and what "done" means, in writing.
- Review. I read the code and traces, run targeted checks, and interview the builders. You get a mid-point note if anything urgent turns up.
- Read-out. Written report and a working session to walk through it.
Principles I hold the work to:
- Bounded authority rather than assumed autonomy
- Deterministic checks around probabilistic behaviour
- Human control over consequential actions
- Evidence before confidence, and honest treatment of failure
- Not every workflow needs an agent. Sometimes the finding is "use a script".
FAQ
What does it cost?
A fixed fee, quoted within two working days of your brief and agreed in writing before anything starts. No hourly meter.
What access do you need?
Read access to the code and configuration, a sample of traces or run logs, and one or two hours with the engineers who built it. No production write access, ever.
Will you sign an NDA?
Yes. Findings are yours; nothing from an engagement appears in my writing without your explicit written consent.
Which stacks do you cover?
Python and TypeScript agent systems, custom harnesses, LangChain/LangGraph-style frameworks, RAG pipelines, and containerised sandboxes. Model-vendor neutral.
Where are you based?
Remote · UK / EU time zones. Engagements run remotely, in English.
Contact
The fastest start is a short written brief: the system, what worries you, what it can access, and your constraints. The email button below opens a template with those questions.
Or write directly: [email protected]. Replies within two working days.